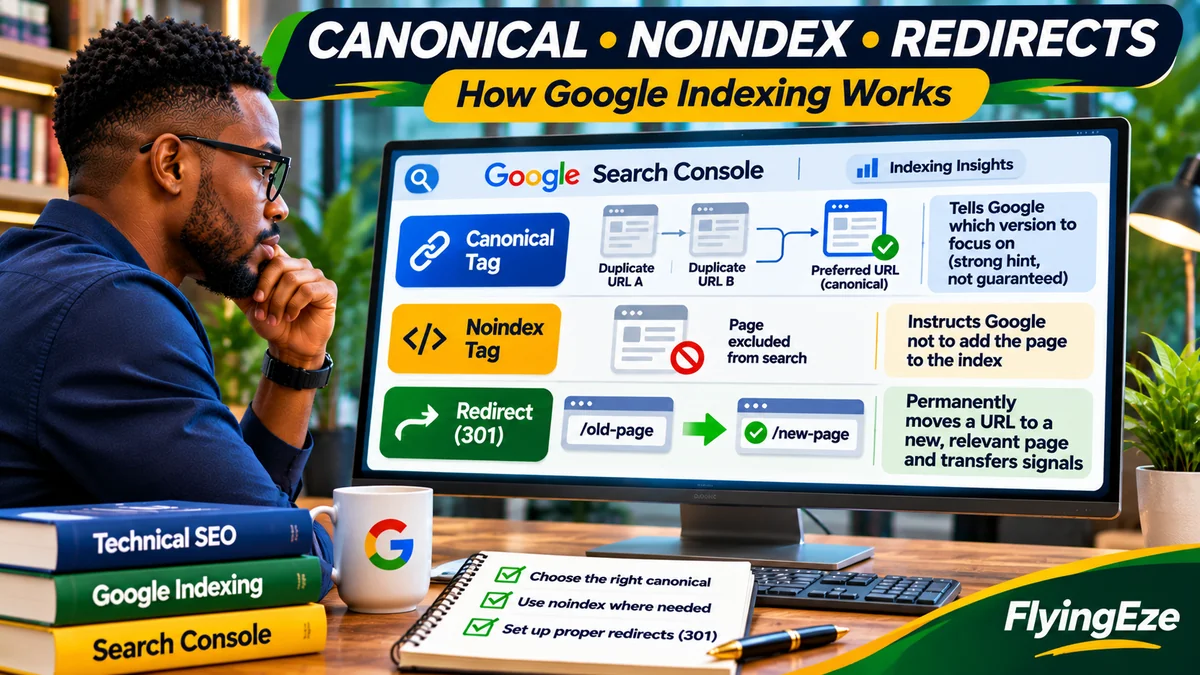
Canonical tags, noindex directives and redirects affect Google indexing in different ways: a canonical tag suggests which duplicate URL Google should prefer, a noindex directive tells Google not to include a crawled page in Search, and a redirect sends visitors and crawlers to another URL. Choosing the wrong method can keep an important article out of Google, cause duplicate URLs to compete for attention or move users to an unintended page.
Consider a Nigerian news website where one article is available under two URL paths, a development setting accidentally adds noindex, and an old slug redirects to the homepage. The publishing team might see three different Search Console exclusions, but the solutions are not interchangeable. Google's canonicalisation guidance treats redirects and canonical annotations as strong signals for a preferred URL, while its noindex documentation describes an explicit index-exclusion instruction.
This practical guide explains the distinction, shows technical examples and provides a checklist for publishers, e-commerce stores and other business websites. Research verified 3 November 2026 against Google Search Central and Search Console documentation.
Canonical vs noindex vs redirect: the quick comparison
| Method | Main purpose | What happens to visitors? | Google indexing implication |
|---|---|---|---|
rel="canonical" | Signal a preferred URL among duplicate or substantially similar pages | Visitors stay on the current URL | Strong hint, not a command; Google can choose differently |
noindex | Exclude a page from search results | Page can remain accessible | Google removes/excludes it after crawling and seeing the directive |
| 301 / 308 | Move a URL permanently | Automatically sent to destination | Strong signal that destination should be canonical |
| 302 / 307 | Move a URL temporarily | Automatically sent to temporary destination | Does not signal that destination should replace source as canonical |
None of these methods forces Google to index a preferred destination. The destination must still be accessible and eligible, and Google ultimately makes its own indexing and canonical decisions. Google's redirect documentation distinguishes permanent and temporary moves; its Page indexing report explains why many alternate, excluded or redirected URLs should not be indexed in the first place.
1. Canonical tags: tell Google which version you prefer
A canonical tag is an HTML link element usually placed in the document's <head>. It identifies the primary version of a page when equivalent content is accessible through different URLs. A product might appear with tracking parameters or sorting variants; a publisher might accidentally expose both /news/story and /story.
For example, the preferred article could contain:
<link rel="canonical" href="https://example.com/business/payment-guide">A duplicate version can use the same preferred canonical URL. The tag does not redirect readers. They can still visit the alternate address, but Google receives a strong signal to consolidate indexing signals around the nominated representative. Google's official guide explains that rel="canonical" is strong, while inclusion in an XML sitemap is a weaker canonical hint.
When should you use a self-referencing canonical?
For a unique, indexable article, pointing its canonical tag to its own preferred public URL helps express your intent consistently. Use an absolute HTTPS URL and confirm that the target returns the correct content without an accidental redirect or noindex directive. Self-reference is a useful convention, not a requirement that guarantees indexing.
For example, an article at https://example.com/technology/ai-tools should not accidentally declare https://example.com/ as its canonical because a CMS template reused a homepage setting. A mistake like that can undermine an article's visibility.
When can Google ignore your chosen canonical?
Google may select a different URL if its content, internal links, redirects and technical signals disagree with your declared preference. It may also group the page with a more similar page than the one you nominated. Use Search Console's URL Inspection tool to compare User-declared canonical and Google-selected canonical where available. The canonical troubleshooting guide recommends inspecting technical signals and determining whether Google's selection actually makes sense.
Do not attempt to canonicalise two genuinely different articles to one generic page simply because they target related keywords. If their main content and search intent are distinct, each may warrant its own indexable canonical URL.
2. Noindex: deliberately exclude a page from Google's index
A noindex directive tells supporting search engines not to index an accessible page. It is suitable when you intentionally do not want a page to appear in search results, such as a thin internal-search result page or a duplicate landing page that should remain accessible but not searchable. Whether to use it depends on the site's publishing and navigation strategy.
The HTML form is:
<meta name="robots" content="noindex">A server may instead send an HTTP response header:
X-Robots-Tag: noindexThe header is particularly useful for non-HTML resources, such as PDFs. Google's noindex instructions state that the meta element and HTTP header have equivalent indexing effects when detected. A page carrying noindex will not appear in Google Search once Google can crawl and process the directive—even if external sites link to it.
Why noindex and robots.txt should not be confused
robots.txt controls crawling; noindex controls index inclusion. If robots.txt blocks Googlebot from the page, Google may never see the noindex instruction. In some circumstances, a URL can still be known or even indexed based on external references despite a robots block. Therefore do not use robots.txt to enforce noindex.
Google's robots.txt guidance explains that the file is not a reliable way to hide content from search results. For confidential drafts, customer records or private dashboards, enforce authentication and access control. A noindex tag is not a security or privacy mechanism.
When noindex causes an accidental publishing problem
News sites often pre-render articles in draft mode and later switch them to published. If the CMS or CDN retains a noindex header after publication, Google can crawl a perfectly readable article and still exclude it. Other frequent mistakes include production-wide noindex flags copied from staging, index directives applied to all paginated category pages, or conflicting directives injected by a plugin.
Check the live HTTP headers and rendered HTML, remove the unintended directive, confirm normal access and then request reindexing selectively. Do not assume a page is fixed simply because its HTML template contains no noindex tag: a proxy or middleware response header can override that assumption.
3. Redirects: send old URLs to their new locations
A redirect tells the browser and crawler that a requested URL should resolve somewhere else. The most common SEO choices are 301 and 308 for permanent moves, and 302 and 307 for temporary moves. Google treats permanent redirects as strong signals favouring the destination as canonical. Temporary redirects normally do not convey that same preference, although other signals can still influence which page Google indexes. Google's redirect guidance prefers server-side redirects where practical.
For a permanent move from /old-guide to /new-guide, an Apache configuration might use:
Redirect 301 /old-guide https://example.com/new-guideAn Nginx location could use:
location = /old-guide { return 301 https://example.com/new-guide;
}
These are illustrative patterns; test them in the context of the actual virtual host, routing rules and query-string behaviour before deploying. A 308 redirect is also permanent. The HTTP method-preservation differences between status codes can matter for APIs or form submissions, although ordinary article-page redirects mostly involve GET requests.
Use temporary redirects only when the move is genuinely temporary
Imagine a maintenance page temporarily replacing a service URL. A 302 or 307 may be suitable so the original URL remains the preferred one when service resumes. If a publisher permanently changes an article slug, a 301 or 308 usually expresses the intention more clearly. Do not use temporary redirects indefinitely while expecting Google to treat them exactly like a permanent move.
Do not redirect deleted articles indiscriminately to the homepage
When an old article has a closely relevant replacement, redirect it to that resource. If it is gone and there is no appropriate substitute, a genuine 404 or 410 may be the right response. Sending all removed URLs to the homepage creates a poor experience and can be interpreted as a soft 404 or other unhelpful behaviour.
Also inspect redirect chains and loops. An old slug that redirects through several intermediate URLs before reaching an indexable article wastes requests and can trigger Search Console redirect errors. Prefer direct old-to-final redirects, update internal links to the final URL and test both old and destination addresses.
4. Why combining canonical and noindex can send conflicting signals
A common mistake is to add noindex to a duplicate page and also declare a canonical pointing to another URL, expecting Google to transfer all of the duplicate's signals to the preferred page. Google's guidance says do not use noindex to prevent selection of a canonical URL within a site: noindex blocks that page from search rather than serving as a reliable canonicalisation method.
For accessible duplicate pages that must remain usable, a canonical annotation is generally the clearer tool. For an old URL being retired, a permanent redirect is usually clearer. Use noindex when you truly want an accessible page excluded without relying on it to consolidate canonical signals. The canonical methods documentation distinguishes these intentions.
Another conflict occurs when the primary page declares itself canonical but also receives X-Robots-Tag: noindex. The canonical does not cancel the exclusion instruction. Fix the noindex setting before assuming the preferred page should be indexed.
5. A practical URL strategy for articles, products and filters
| Situation | Usually appropriate action | Why |
|---|---|---|
| Published article at its preferred URL | Indexable 200 page, optional self-canonical | Expresses the canonical preference clearly |
| Duplicate article reachable under a second path | 301/308 if retiring it; otherwise canonical to preferred version | Consolidates duplicate URL signals |
| Tracking parameter variant | Canonical to clean preferred URL when content is equivalent | Prevents unnecessary competing variants |
| Site-search results page not intended for indexing | Noindex if accessible and appropriate | Keeps an unwanted page out of Search |
| Old article moved permanently | 301 or 308 to genuinely relevant replacement | Moves users and signals permanent change |
| Temporary maintenance redirect | 302 or 307 | Signals a temporary destination |
| Removed article with no replacement | 404 or 410 | Correctly reports missing content |
| Private account or staff page | Authentication/access control | Search directives are not security controls |
This is a starting decision framework, not a rule that every website should noindex all filters or redirect every similar article. E-commerce facets, pagination and multilingual pages need particular care so valuable URLs remain discoverable and users can navigate properly.
6. How these settings appear in Google Search Console
Open Indexing → Pages in Search Console and review the reasons under Why pages aren't indexed. Google's Page indexing help describes statuses including Alternate page with proper canonical tag, Duplicate, Google chose different canonical than user, Excluded by noindex tag, and Page with redirect. These can be expected outcomes rather than errors.
If an alternate URL is excluded while its intended canonical is indexed, the result may be correct. Similarly, an old redirected URL does not need to remain independently indexed. By contrast, the main article appearing as excluded by noindex or a surprising Google-selected canonical merits investigation.
Inspect the exact URL using URL Inspection . Compare the recorded page with a live test; recent fixes may not appear until Google recrawls. Pay special attention to the user-declared and Google-selected canonical fields in stored inspection information. Google's live test cannot predict canonical selection.
7. Technical audit: check HTML, headers and redirect chains
For a canonical article, check four things together: the HTML canonical annotation, HTTP response headers, effective response status and the final destination after redirects. A clean-looking page source does not rule out an accidental noindex header or CDN redirect rule.
These read-only shell commands can help inspect public responses:
curl -I https://example.com/business/guide
curl -IL https://example.com/old-guide
curl -s https://example.com/business/guide | grep -i canonical
The first shows response headers, the second follows redirects and the third searches the returned HTML for canonical markup. They do not necessarily show what Googlebot received on its last crawl, particularly behind bot protection or JavaScript rendering. Use Search Console and verified server/CDN logs to corroborate findings.
On a Laravel or other CMS-driven site, build a publishing test that checks a page transitions from draft to published without retaining noindex or unintended redirects. Inspect both origin and CDN output after deployment. If a template changes canonical URLs, confirm sitemaps and internal links are updated consistently.
8. Common indexing mistakes and their fixes
Canonical points to homepage: correct it to the actual preferred content URL. Published article still noindex: check application flags and HTTP headers, then remove the unintended directive. Robots blocks noindex: allow crawling where Google must read the exclusion instruction. Permanent move implemented as temporary: switch to the suitable permanent redirect when the change is final.
Redirect loop or long chain: point obsolete URLs directly to the final destination. Deleted post redirects to unrelated category: use a relevant replacement or a proper 404/410. Duplicate sitemap URLs: include the preferred canonical versions rather than all tracking variants. Multiple contradictory canonical tags: remove conflicts and confirm that the target page is accessible and relevant.
Remember that Google may still choose a different canonical after technical repairs, because similarity and content quality also matter. Its troubleshooting guidance recommends investigating both signals and content. As FlyingEze previously explained in AI Search Has Not Made SEO Fundamentals Obsolete , accessibility, page structure and genuinely useful information remain central to discoverability.
9. Worked example: cleaning up a Nigerian publisher's URL changes
Imagine a fictional business site publishes /money/payment-gateways-2026. A marketing campaign adds ?utm_source=newsletter, creating a second accessible URL showing the same article. The clean article should remain indexable, while the parameter version can declare the clean URL as canonical. Readers can use the tracking URL without the publisher treating it as a separate article.
Later the editor changes the article slug to /money/nigeria-payment-gateways permanently. A 301 redirect from the old path to the new path, together with updated internal links, sitemap entries and canonical annotation, clearly expresses the move. If the new page accidentally retains noindex from draft mode, however, the redirect does not guarantee the new destination's indexing.
Now assume the old article was removed entirely and there is no equivalent replacement. Returning a real 404/410 is preferable to sending readers to an irrelevant homepage. Each scenario requires a different tool because each has a different editorial intent.
10. Post-deployment checklist for FlyingEze and other publishers
- Decide which canonical URL should represent every important article or product.
- Check the chosen URL serves the expected content with an appropriate 200 response and no unintended noindex directive.
- Ensure canonical annotations, internal links, sitemaps and permanent redirects agree wherever applicable.
- Verify removed, replaced and temporarily unavailable URLs return the correct status rather than blanket redirects.
- Test effective origin/CDN response headers and redirect chains on desktop and mobile URLs where relevant.
- Use URL Inspection for representative URLs; compare stored indexing and live-test results.
- Request indexing selectively after important corrections, then monitor recrawling and indexed status without assuming instant results.
Google's recrawl guidance says that repeated indexing requests do not accelerate crawling and inclusion cannot be guaranteed. Treat Search Console's exclusion count as a diagnostic starting point, not a target that must fall to zero.
On Cloudflare-protected websites, remember that rules affecting search crawlers differ from policies targeting AI-training bots. FlyingEze's report on Cloudflare and search visibility provides additional context, but individual WAF rules should be audited against actual crawler access before changes are made.
Frequently asked questions
Does a canonical tag guarantee Google will index the preferred URL?
No. It is a strong signal for selecting a canonical among similar pages, not a command to index. Google can choose a different URL based on the full set of signals.
Can I use noindex and a canonical tag together?
The directives can coexist technically, but noindex is not a recommended canonicalisation method. If the goal is to consolidate duplicate URLs, use an appropriate canonical or redirect instead.
Is robots.txt Disallow the same as noindex?
No. Disallow restricts crawling; noindex excludes a page after Google is able to fetch and process the directive. A robots block can prevent Google from seeing noindex.
Which is better for permanently changing an article URL: 301 or 302?
Use 301 or 308 for a permanent move. A 302 or 307 indicates the change is temporary and does not itself signal that the new destination should become canonical.
Why does Search Console say “Page with redirect”?
Google found that URL redirects elsewhere. The redirect source normally is not indexed independently. Inspect the destination to see whether the page you actually want can be indexed.
Can noindex protect confidential business information?
No. Noindex affects search inclusion, not user access. Use authentication, authorisation and appropriate data protection controls for private information.
Conclusion
Choose the indexing control that matches your real intention. Use canonical tags when duplicate URLs should remain accessible but one should be preferred; use noindex when a crawlable page should be excluded; use permanent redirects when a URL has moved for good; and temporary redirects for genuinely temporary changes. Then verify the result in response headers, HTML and Search Console. Consistent signals support better indexing decisions, but no technical directive guarantees Google will rank or index every page.