
Cloudflare Lets Websites Block AI Training Without Leaving Search
Cloudflare's Disallow AI Training setting separates traditional search discoverability from AI-training permission for mixed-use crawlers such as Googlebot, Bingbot and Applebot.
 Written byEze Chidiebere Paul
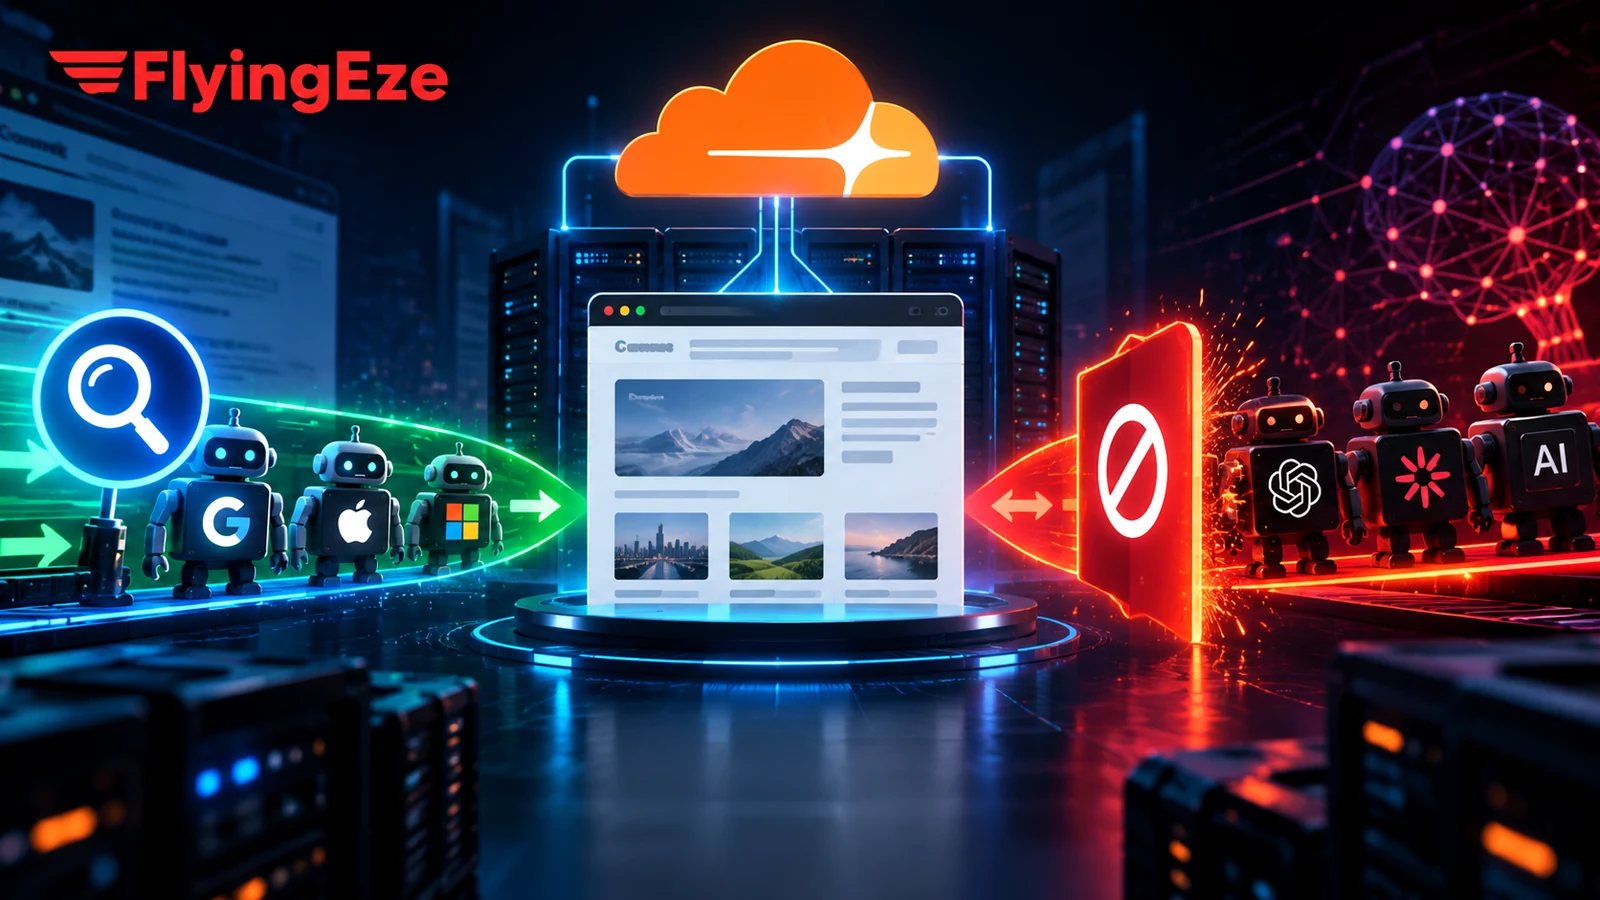
Cloudflare has introduced a new control designed to address one of the web’s growing AI-era problems: how to stay visible in search without automatically allowing the same crawler to use site content for AI training.
Announced on 15 September 2026, Disallow AI Training is intended for mixed-use crawlers that may serve both traditional search and AI-related purposes.
The problem with mixed-use crawlers
Some large internet companies use crawlers that perform more than one function. A crawler may help index pages for search while also supporting AI-training workflows.
That creates a difficult choice for publishers. Blocking the crawler entirely can protect content from unwanted use, but it can also remove the site from traditional search discovery.
What Cloudflare’s new setting changes
Cloudflare says the Disallow AI Training option lets a site express a different preference for training while keeping traditional search access available.
The setting forms part of Cloudflare’s broader Bot Management and AI Crawl Control changes. Cloudflare says its network can identify crawlers, classify their purpose, publish site preferences and block crawlers that do not honour those choices.
Cloudflare’s “Accountable” crawler designation
Cloudflare also introduced an Accountable designation for crawler operators that meet, or commit to meeting, a set of requirements around publisher control and transparency.
Those requirements include a way for site owners to opt out of AI training, controls for AI summaries, visibility into which URLs were made available for training, and assurance that opting out of training will not reduce traditional search visibility.
Cloudflare says Apple, Google and Microsoft meet the designation through a combination of capabilities already available and time-bound commitments still being implemented.
Why this matters for SEO and publishers
For publishers, the change attempts to separate two decisions that were increasingly becoming entangled: whether a search engine may index a page and whether the same organisation may use that page to train AI systems.
That distinction matters for news sites, blogs, forums, educational publishers and businesses that depend on search traffic but want more control over how their content contributes to AI models.
It is not a universal guarantee
The setting does not mean every crawler on the internet will automatically comply. Cloudflare’s approach depends on identifying crawler behaviour, enforcing network-level controls where possible, and tracking whether operators honour declared preferences.
Website owners should therefore treat the control as part of a broader bot-management strategy rather than a replacement for monitoring, robots directives and access policies.
What Cloudflare customers should review
- Whether traditional Search traffic should remain allowed.
- Whether AI Training should be allowed or disallowed.
- How Agent crawlers should be handled, especially on ad-supported pages.
- Whether existing bot settings were migrated as expected.
- How crawler behaviour appears in Cloudflare Radar and site analytics.
The bigger shift
The web is moving toward more granular crawler permissions. Instead of a single allow-or-block decision, publishers increasingly need separate controls for search indexing, AI training, summaries and autonomous agents.
Cloudflare’s new setting is an attempt to make that distinction practical at the network edge while preserving the search visibility many websites still depend on.
Continue reading
Dangote Refinery IPO Rush Exposes Stress Points in Nigeria’s Fintech Infrastructure
The Dangote Refinery IPO overwhelmed several Nigerian investment platforms, exposing fintech scaling and third-party risks while widening retail market access.
Anthropic Weighs New AI Model as OpenAI’s GPT-6 Astra Intensifies Enterprise Race
Anthropic is considering a new AI model as OpenAI’s GPT-6 Astra gains enterprise momentum, raising questions about safety, competition and IPO timing.
Google Ads Adds Spend Benchmarks to Compare Your Budget With Similar Advertisers
Google Ads is surfacing a Spend Benchmarks report that compares weekly ad spend and clicks with similar businesses, offering context rather than a profitability target.
OpenAI Turns ChatGPT Ads Into Conversations With Sponsored Agents
OpenAI is testing Sponsored Agents in ChatGPT Ads with selected US advertisers, alongside new AI campaign tools and HubSpot and Shopify integrations.