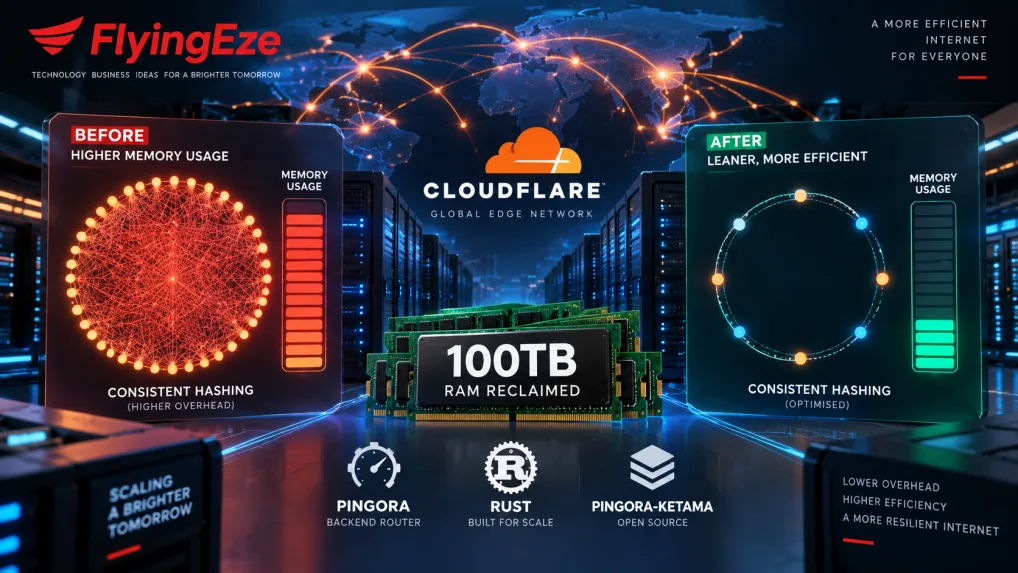
Cloudflare says a targeted optimisation in one of its Pingora-based services has reclaimed more than 100TB of RAM across its global network. The result came not from replacing the system wholesale, but from examining how much memory its consistent-hashing implementation consumed and asking whether every byte and every hash point was actually earning its place.
The work centres on Pingora Backend Router, an internal load-balancing service that uses Cloudflare's open-source pingora-ketama library. The library implements consistent hashing, a technique widely used in distributed systems to route work to servers while minimising disruption when the pool of servers changes.
Why consistent hashing was using so much memory
Cloudflare uses consistent hashing to help route cacheable requests to servers by URL. In simple terms, requests and servers are mapped into the same hash space, allowing the system to make stable routing decisions even when individual machines are added or removed.
At Cloudflare's scale, however, the number of structures involved becomes enormous. The company said Pingora Backend Router was using substantially more memory than expected in data associated with pingora-ketama. That prompted engineers to examine both the representation of each hash entry and the number of hash points being created for every server.
The first win came from shrinking each entry
One part of the optimisation was distinctly low level. Cloudflare found that a hash entry stored a 32-bit hash and a 32-bit server index. But because no Cloudflare data centre needs an index space anywhere close to the full 32-bit range, the server index could be represented with fewer bytes.
The revised representation reduced the memory used by the consistent-hashing entries by about 25%, according to Cloudflare. The important lesson is broader than Rust or Cloudflare: data structures that look trivial in isolation can become expensive when repeated across a hyperscale fleet.
Then Cloudflare challenged how many hashes it really needed
The larger saving came from questioning an assumption about load distribution. Consistent-hashing systems commonly create multiple hash points for each server so that traffic is spread more evenly. More points generally improve balance, but the improvement eventually becomes very small.
Cloudflare derived the statistical relationship between the number of hash points and the variation in load distribution. In its example, moving from 10,000 to 100,000 hashes per server produced only a small additional reduction in error. The company also noted that because its implementation uses 32-bit hashes, collisions become more important as the total number of points rises.
With that analysis in hand, Cloudflare concluded it could reduce the number of generated hashes per server by 90% without a meaningful loss of balancing quality for its use case.
Why the rollout had to be careful
A smaller hash ring creates a second problem: it can change which backend receives a cacheable request. If a global network suddenly changes those assignments everywhere, many cached objects may appear to move at once. That can drive a surge of requests back to origin servers.
Cloudflare therefore ran the old and new rings side by side during the migration. Its normal rollout framework could decide which version handled each request, giving engineers a clean rollback path if anything behaved unexpectedly.
The company says it started with small validation locations, expanded through progressively larger groups of data centres and monitored backend selection, connection errors, process memory, startup time, cache behaviour and origin traffic. Only after the migration reached full deployment did it remove the old large hash rings.
The result: more than 100TB of RAM reclaimed
Cloudflare says the combined changes reduced Pingora Backend Router's memory use by more than 100TB globally. That came on top of a separate optimisation announced in August in which its DNS team said it freed roughly another 100TB by changing the memory layout of its 1.1.1.1 DNS cache.
The numbers are unusually large because Cloudflare operates thousands of servers with petabytes of memory. A change that saves a small amount per process or per node can therefore become a fleet-wide saving measured in tens or hundreds of terabytes.
What developers and infrastructure teams can learn from it
The most useful takeaway is not that every system should copy Cloudflare's exact hash-count settings. Workloads, server pools and acceptable balancing error differ. The stronger lesson is that infrastructure teams should periodically test assumptions that were inherited from libraries, defaults or earlier hardware constraints.
Three questions are especially useful: does a data field really need its current width, does adding more replicas or hash points still materially improve the result, and can a change be rolled out in a way that limits the blast radius if an assumption turns out to be wrong?
Cloudflare has made the revised behaviour available in the open-source pingora-ketama crate through a version-two ring implementation. The older ring remains available, allowing both approaches to coexist during migration.
That matters beyond this particular optimisation because Pingora now underpins more of Cloudflare's production stack. In May, Cloudflare said its cache had moved to a proxy built on Pingora, the Rust-based framework already used for a substantial portion of its network traffic.
FlyingEze has also recently covered Cloudflare's controls for blocking AI training while remaining discoverable in search , another example of the company changing low-level infrastructure behaviour while trying to preserve compatibility with existing web workflows.
Bottom line
Cloudflare's 100TB saving is a useful example of performance engineering at scale: profile a real bottleneck, challenge the mathematics behind a long-standing default, shrink data structures where the range allows it, and roll the change out conservatively enough that the cure does not create a larger production problem.
For most teams, the absolute saving will be nowhere near 100TB. But the engineering principle scales down just as well as it scales up: when a structure is created millions of times, a few unnecessary bytes can be worth investigating.